Privacy and Compliance
8 min readHow to use frontier AI on your data without exposing PII
Most firms don't need to train their own AI model to use AI safely on their data. What they need is a scrub-and-send pipeline in front of a model that already exists: scrub personal information (PII) locally, send placeholders, log every request, restore the real values on return. Here is how the pipeline works, when the expensive options earn their place, and how it lines up with Canadian and UK privacy rules.
Every few weeks someone tells a firm it needs its own AI model. Most don't. What a firm usually needs is a clean pipeline in front of a model that already exists. Using AI on your own data is a privacy problem and a plumbing problem, and training a model fixes neither. Let the labs with the deep pockets keep improving the models. Most of us should just be customers of theirs.
I run HuCortex. We support firms across a lot of industries, and I'll use an accounting firm as the example here because it's the hardest case I see often: SINs, bank accounts, payroll files, other people's whole financial lives. The same approach works for any business that holds personal information about its customers or staff. The question I get, in one form or another, is whether they have to train their own model to keep that data safe. Usually not. The check at the end of this article will tell you where your own setup stands.
One note on words before we start. PII is the everyday shorthand for personally identifiable information. Canadian law says personal information, UK law says personal data. I'll say PII when I mean the data and use the legal term when a specific law is on the table.
The model was never the problem
Give a current frontier model a few good examples in the prompt and it will categorize transactions, summarize a trial balance and draft a decent letter. Skill is rarely what's missing.
What's missing is a way to hand it real work without handing it real identities. People skip that step, hit the wall, and conclude that training is the fix. It isn't. Training teaches a model how to behave. It doesn't give the model your documents and it does nothing to keep names out of your logs.
How does the scrub-and-send pipeline work?
The model never sees a real person. It sees placeholders. Your people see the real values again on the way back out. Six steps, and five of them happen inside your own environment.
- Ingest locally. Documents land on a machine you control. Nothing has left yet.
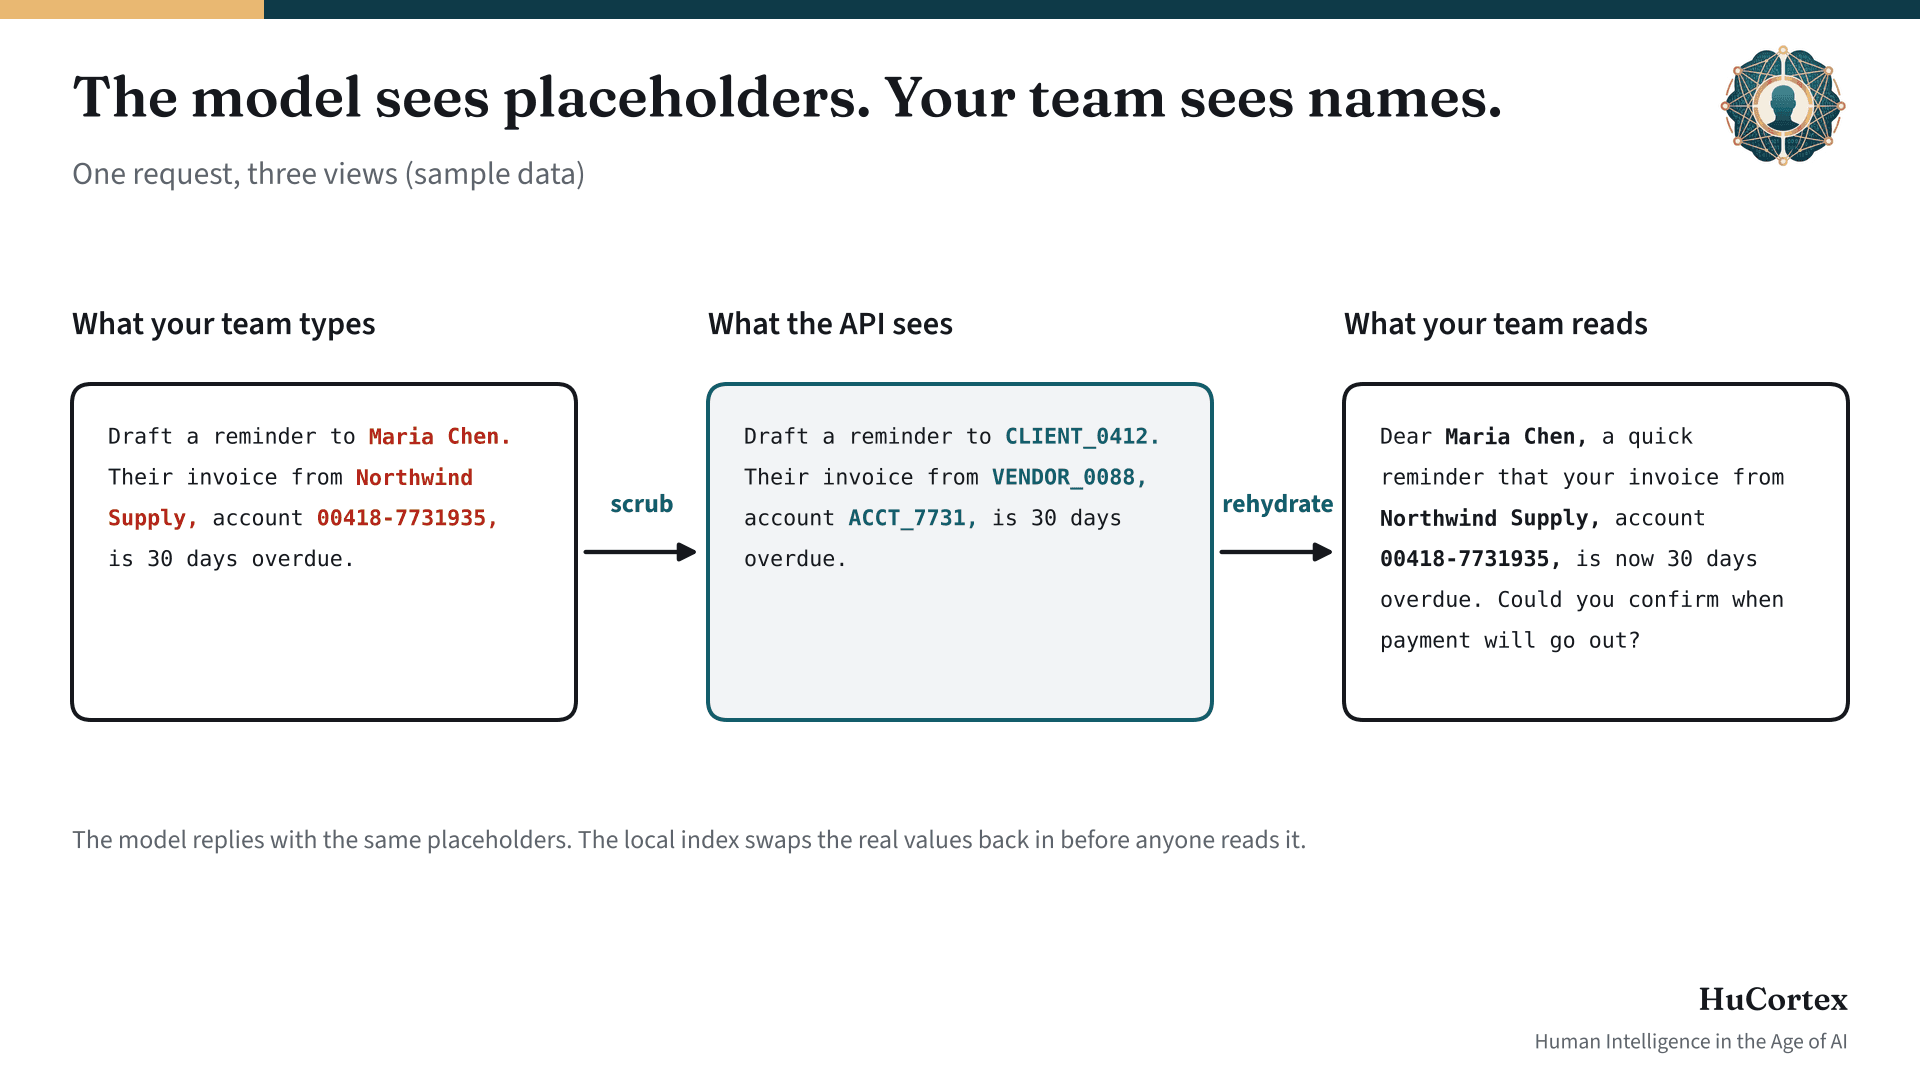
- Scrub. Names, SINs, account numbers, addresses, emails and phone numbers are detected and swapped for placeholders like CLIENT_0412 or ACCT_7731. The label itself doesn't matter. PERSON_0412 works just as well.
- Index. The mapping from placeholder back to real value goes into a local index file. It never goes to the model and never leaves your environment.
- Send. Only the scrubbed text goes to the API.
- Log. Every request and every response is kept as your audit trail. If a regulator asks what you sent, or the person whose record it was asks, you can show them.
- Rehydrate. When the answer comes back, the placeholders are swapped for the real values before a human reads it.
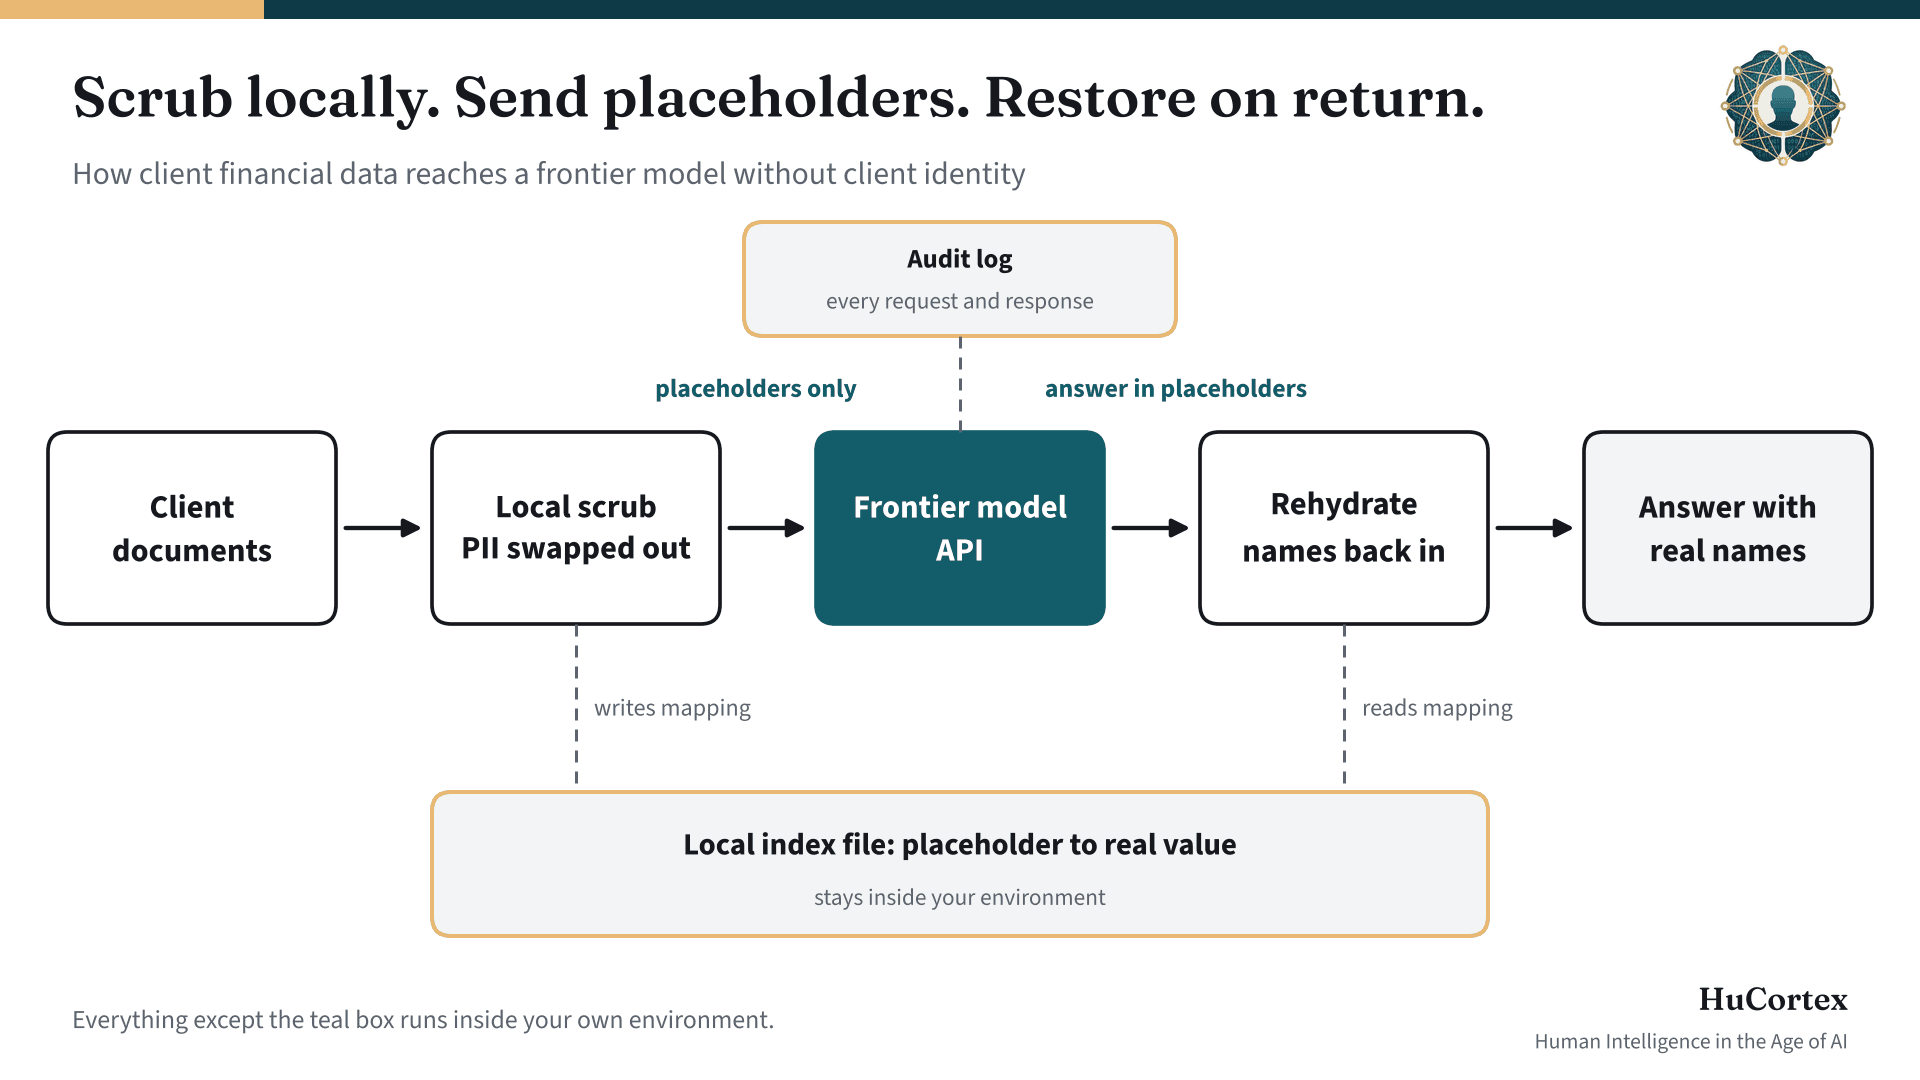
The model reasons about CLIENT_0412 exactly as it would about a real name. The person reading the answer sees real names. Nobody in between does.
Two details that matter more than they look
Because the audit log only ever holds scrubbed payloads, it proves what left your building without turning into a second copy of everyone's identity. That's the good news. Two design choices decide whether the rest holds up.
- Use random or keyed placeholders, never a plain hash. A hash only hides a value that is hard to guess, and a SIN isn't. Anyone who gets hold of the hash can try every possible number on ordinary hardware, and hardware only gets faster.
- Treat the index file as the crown jewel. Encrypt it, restrict who can read it, back it up. It is the one thing that can undo your scrubbing.
When does training or self hosting earn its place?
Rarely, in my experience. Run the cheap, reversible options first and stop at the first one that works. Every step up the ladder adds cost and lock-in, so make each one earn its place against a test set of real examples. The failure you're seeing tells you which step to try next.
- The model is missing information. That's retrieval (RAG): your chart of accounts, your policies, current CRA guidance. Tax rules change every year, and anything baked into model weights goes stale.
- It's wrong even with the information in front of it. Better prompts, better examples, or a stronger model.
- It's right but too expensive at volume. Route the routine work to a small hosted model and escalate the hard cases to a frontier one.
- It's right but inconsistent in format. Structured outputs first. Fine tuning last.
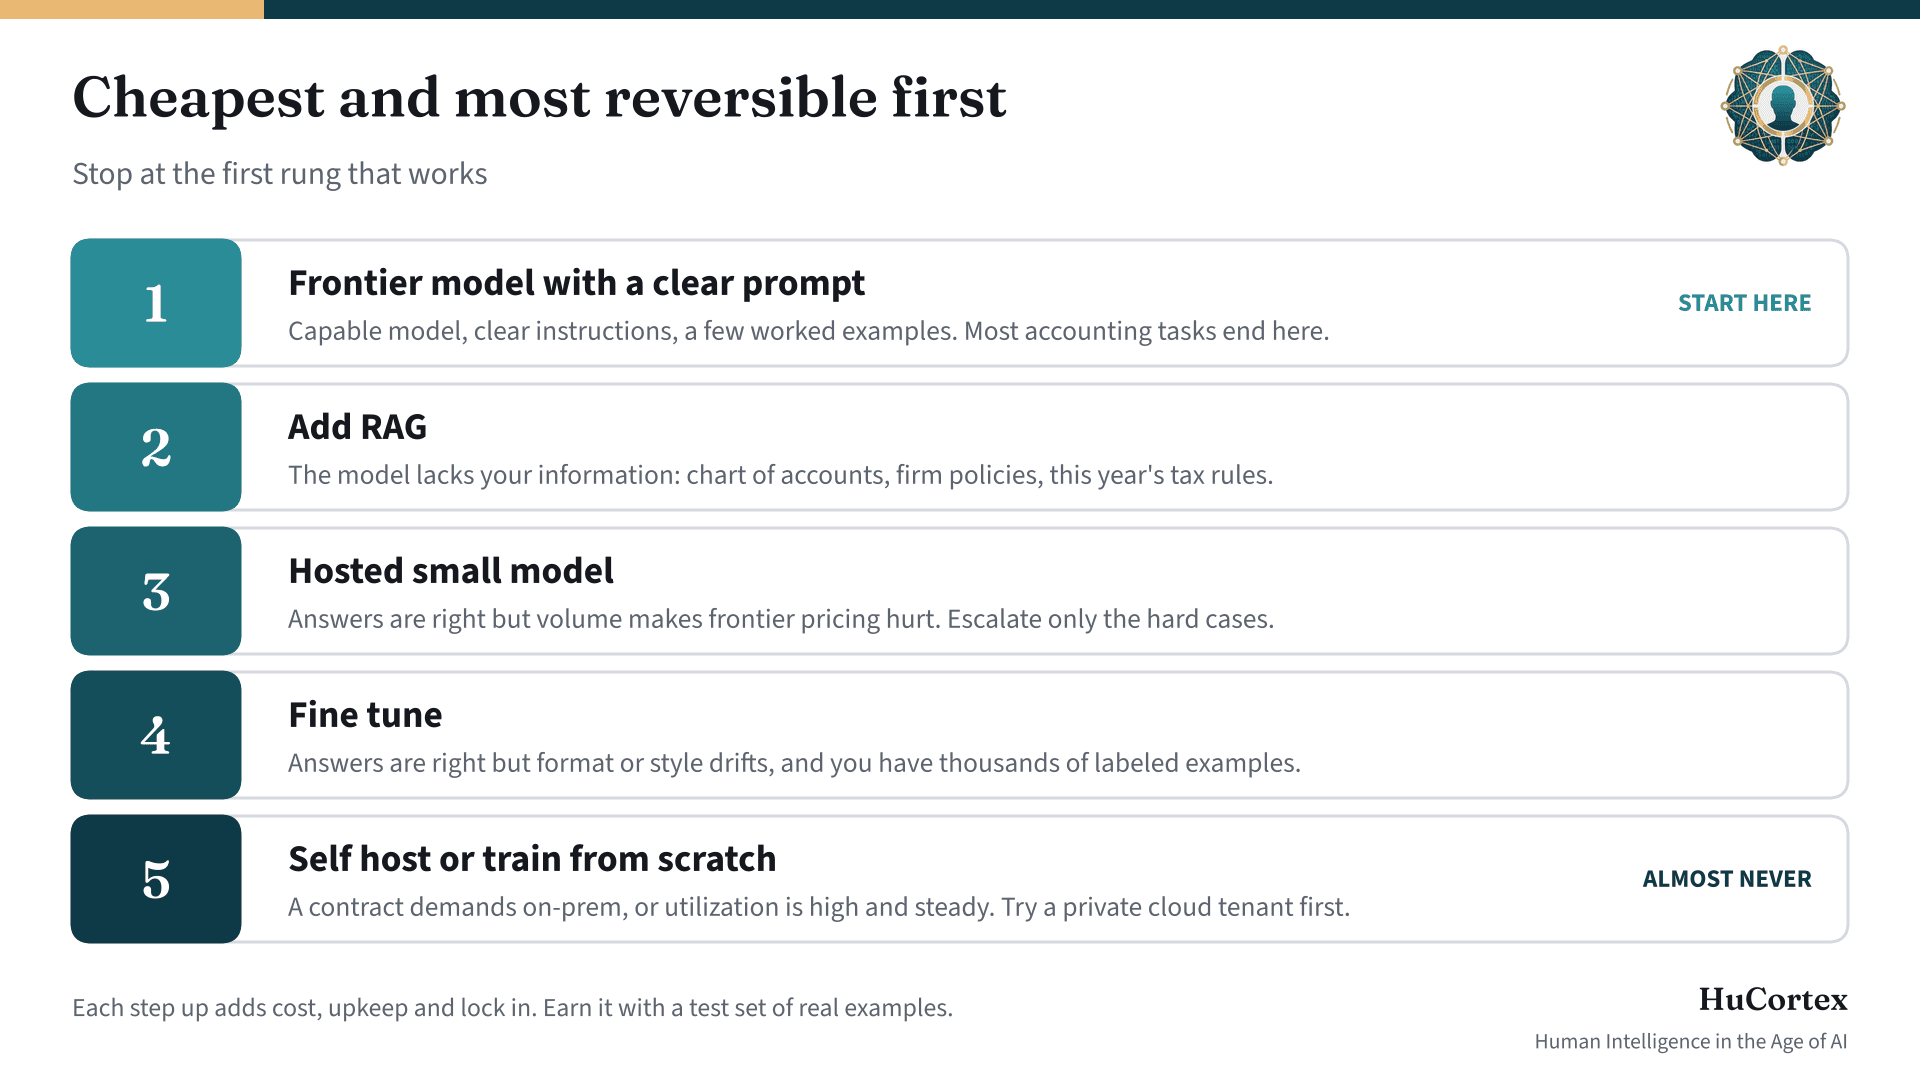
Buying GPUs only pays off if you'll keep them busy most of the day, or if a contract insists on on-prem processing. For most firms the API bill comes in well under the hardware, the power and the engineer who has to keep it all running. Count that engineer honestly. People never do.
If you need more control than a public API gives you, whether because a contract says so or because you'd sleep better, there's a middle option: run a frontier model inside your own cloud tenant, in a region that meets your residency needs. Try that before you buy a single GPU.
A custom model is a weak advantage anyway. Clean data handling, and the trust of the people whose information you hold, are worth more than a model nobody else wants.
This works beyond accounting
Nothing in the pipeline is specific to accounting. Any job where a capable model has to read sensitive material can run the same way. Scrub locally, send placeholders, restore on return.
We run it on our own log reviews at HuCortex. Security and IT logs are full of usernames, hostnames, IP addresses and email addresses. All of that gets swapped for placeholders before a model goes looking for patterns, and swapped back when an analyst reads the findings. Same index file, same audit trail, same rules.
Contracts, HR cases, support tickets and claims files all fit. The test is the same every time: can the model do the job without knowing who is who? Regulated records such as health information carry extra rules of their own, so check those before you copy the approach.
Where can this still go wrong?
This cuts exposure a lot. It doesn't erase it. Missed identifiers, context clues and the key file are risks you keep managing.
- Scrubbing is probabilistic. A name buried in a free-text memo, or an account number in an odd format, can slip through. Measure the miss rate on real documents instead of assuming it's zero.
- Scrubbed text can lose context. Sometimes the vendor name is exactly what tells the model how to categorize a transaction. Test on scrubbed inputs, not clean ones.
- Placeholders don't make data anonymous. If you can still look up who CLIENT_0412 is, regulators in Canada and the UK treat it as personal information. Keep your vendor contracts and zero-retention terms in place.
- Some of the people in your records, and some of the businesses you serve, care where processing happens even when the data is scrubbed. Say so in your privacy notice and your contracts when data is processed outside Canada, and say it early.
How does this line up with Canadian and UK privacy requirements?
I checked the design against the main Canadian and UK requirements in October 2026. This is a practitioner's read, not legal advice, so run anything you put in a notice or a contract past a privacy lawyer. For each requirement, what it says and then how the pipeline lines up.
- PIPEDA identifiability test. Information is personal if there is a serious possibility someone could be identified from it. The vendor sees less, but you hold the key, so treat the data as personal information on your side.
- Quebec Law 25. De-identified means no direct identification; anonymized means identification is irreversible. A reversible mapping is de-identified at best, never anonymized.
- UK GDPR, per the ICO. Pseudonymised data is personal data for whoever holds the key. Same answer if the people in your records are in the UK. A recipient without the key may see it differently.
- PIPEDA cross-border processing. A transfer for processing is a use, not a disclosure. You stay accountable and should tell people foreign authorities may access their information. Vendor contract terms, plus a plain line in your privacy notice.
- Alberta guidance. Give notice when a service provider outside Canada is used. Add it to your privacy notice.
- Quebec impact assessment. A privacy impact assessment before personal information leaves Quebec. Do one if you hold records about people in Quebec. Whether placeholder text counts is unsettled.
- Generative AI principles. Commissioners say to use de-identified data where personal information isn't needed, and to limit retention. Scrubbing matches the first. Your audit log needs a retention schedule.
- Breach reporting (OPC) and Alberta. Report breaches with a real risk of significant harm, and keep breach records. The index file and logs are in scope. Encrypt them and restrict access.
- CPA Ontario guidance. Cites Rule 208: no confidential client information in AI tools unless the environment is verified. If you are a CPA, document how you verified yours.
Two things are still open. I found no regulator guidance on this exact setup, so whether placeholder-only text counts as personal information in the vendor's hands isn't settled. And the law is moving. Bill C-36 was introduced in June 2026, and Alberta is reviewing its private sector privacy act.
The boring version wins
The firms getting this right are, for the most part, not training anything. They built a dull pipeline and they log everything. Ask them what left the building last Tuesday and they can tell you in two minutes. That's the setup I'd want if it were my data.
If you want a quick read on where your own setup sits on that ladder, we built a free five-minute check: DiscoverAI. Ten fixed-choice questions, and the read arrives by email. Your name and email never reach the model. Only the labels behind your answers do, which is this same pipeline applied to the form itself.
Check your setup with DiscoverAICommon questions
- Do we need to train our own AI model to use AI on our data?
- Usually not. A current frontier model already categorizes transactions, summarizes a trial balance and drafts letters with a few examples in the prompt. What most firms need is a pipeline that scrubs personal information before anything is sent and restores it on return, plus an audit log of every request.
- What counts as PII in this setup?
- Anything that identifies a person on its own or in combination: names, SINs, account numbers, addresses, emails and phone numbers, and in security logs usernames, hostnames and IP addresses. Canadian law calls it personal information and UK law calls it personal data. The pipeline scrubs all of it before anything reaches the model.
- What is a scrub-and-send pipeline?
- Six steps: ingest documents locally, scrub names, SINs, account numbers and contact details into placeholders like CLIENT_0412, keep the placeholder-to-real mapping in a local encrypted index file, send only scrubbed text to the API, log every request and response, and rehydrate the answer with real values before a person reads it.
- Are placeholders the same as anonymized data under PIPEDA or Quebec Law 25?
- No. If you can still look up who CLIENT_0412 is, the data is personal information on your side under PIPEDA, de-identified at best under Quebec Law 25, and pseudonymised personal data under UK GDPR. Keep vendor contracts, zero-retention terms and privacy notices in place. Scrubbing reduces exposure, it does not remove obligations.
- When does fine tuning or self hosting make sense?
- Rarely, and usually only after the cheaper steps fail a test on real examples. Missing information is a retrieval problem. Wrong answers call for better prompts or a stronger model. Cost at volume calls for a small hosted model with escalation. Format drift calls for structured outputs first. Self hosting pays only when the GPUs stay busy or a contract demands on-prem processing.
- What is the biggest risk in the pipeline?
- The index file, because it is the only thing that can undo the scrubbing. Encrypt it, restrict who can read it and back it up. After that: scrubbing is probabilistic, so measure the miss rate on real documents, and test the model on scrubbed inputs because removing a vendor name can remove the context it needed.
Sources
- Principles for responsible, trustworthy and privacy-protective generative AI technologies, Office of the Privacy Commissioner of Canada
- Guidelines for processing personal data across borders, Office of the Privacy Commissioner of Canada
- What to do if you experience a privacy breach, Office of the Privacy Commissioner of Canada
- Anonymisation and pseudonymisation guidance, Information Commissioner's Office (UK)
- Commission d'accès à l'information du Québec (Law 25)
Ready to take the next step?
HuCortex works with Canadian businesses on CPCSC readiness, PIPEDA compliance, and managed security. Start with a free assessment.